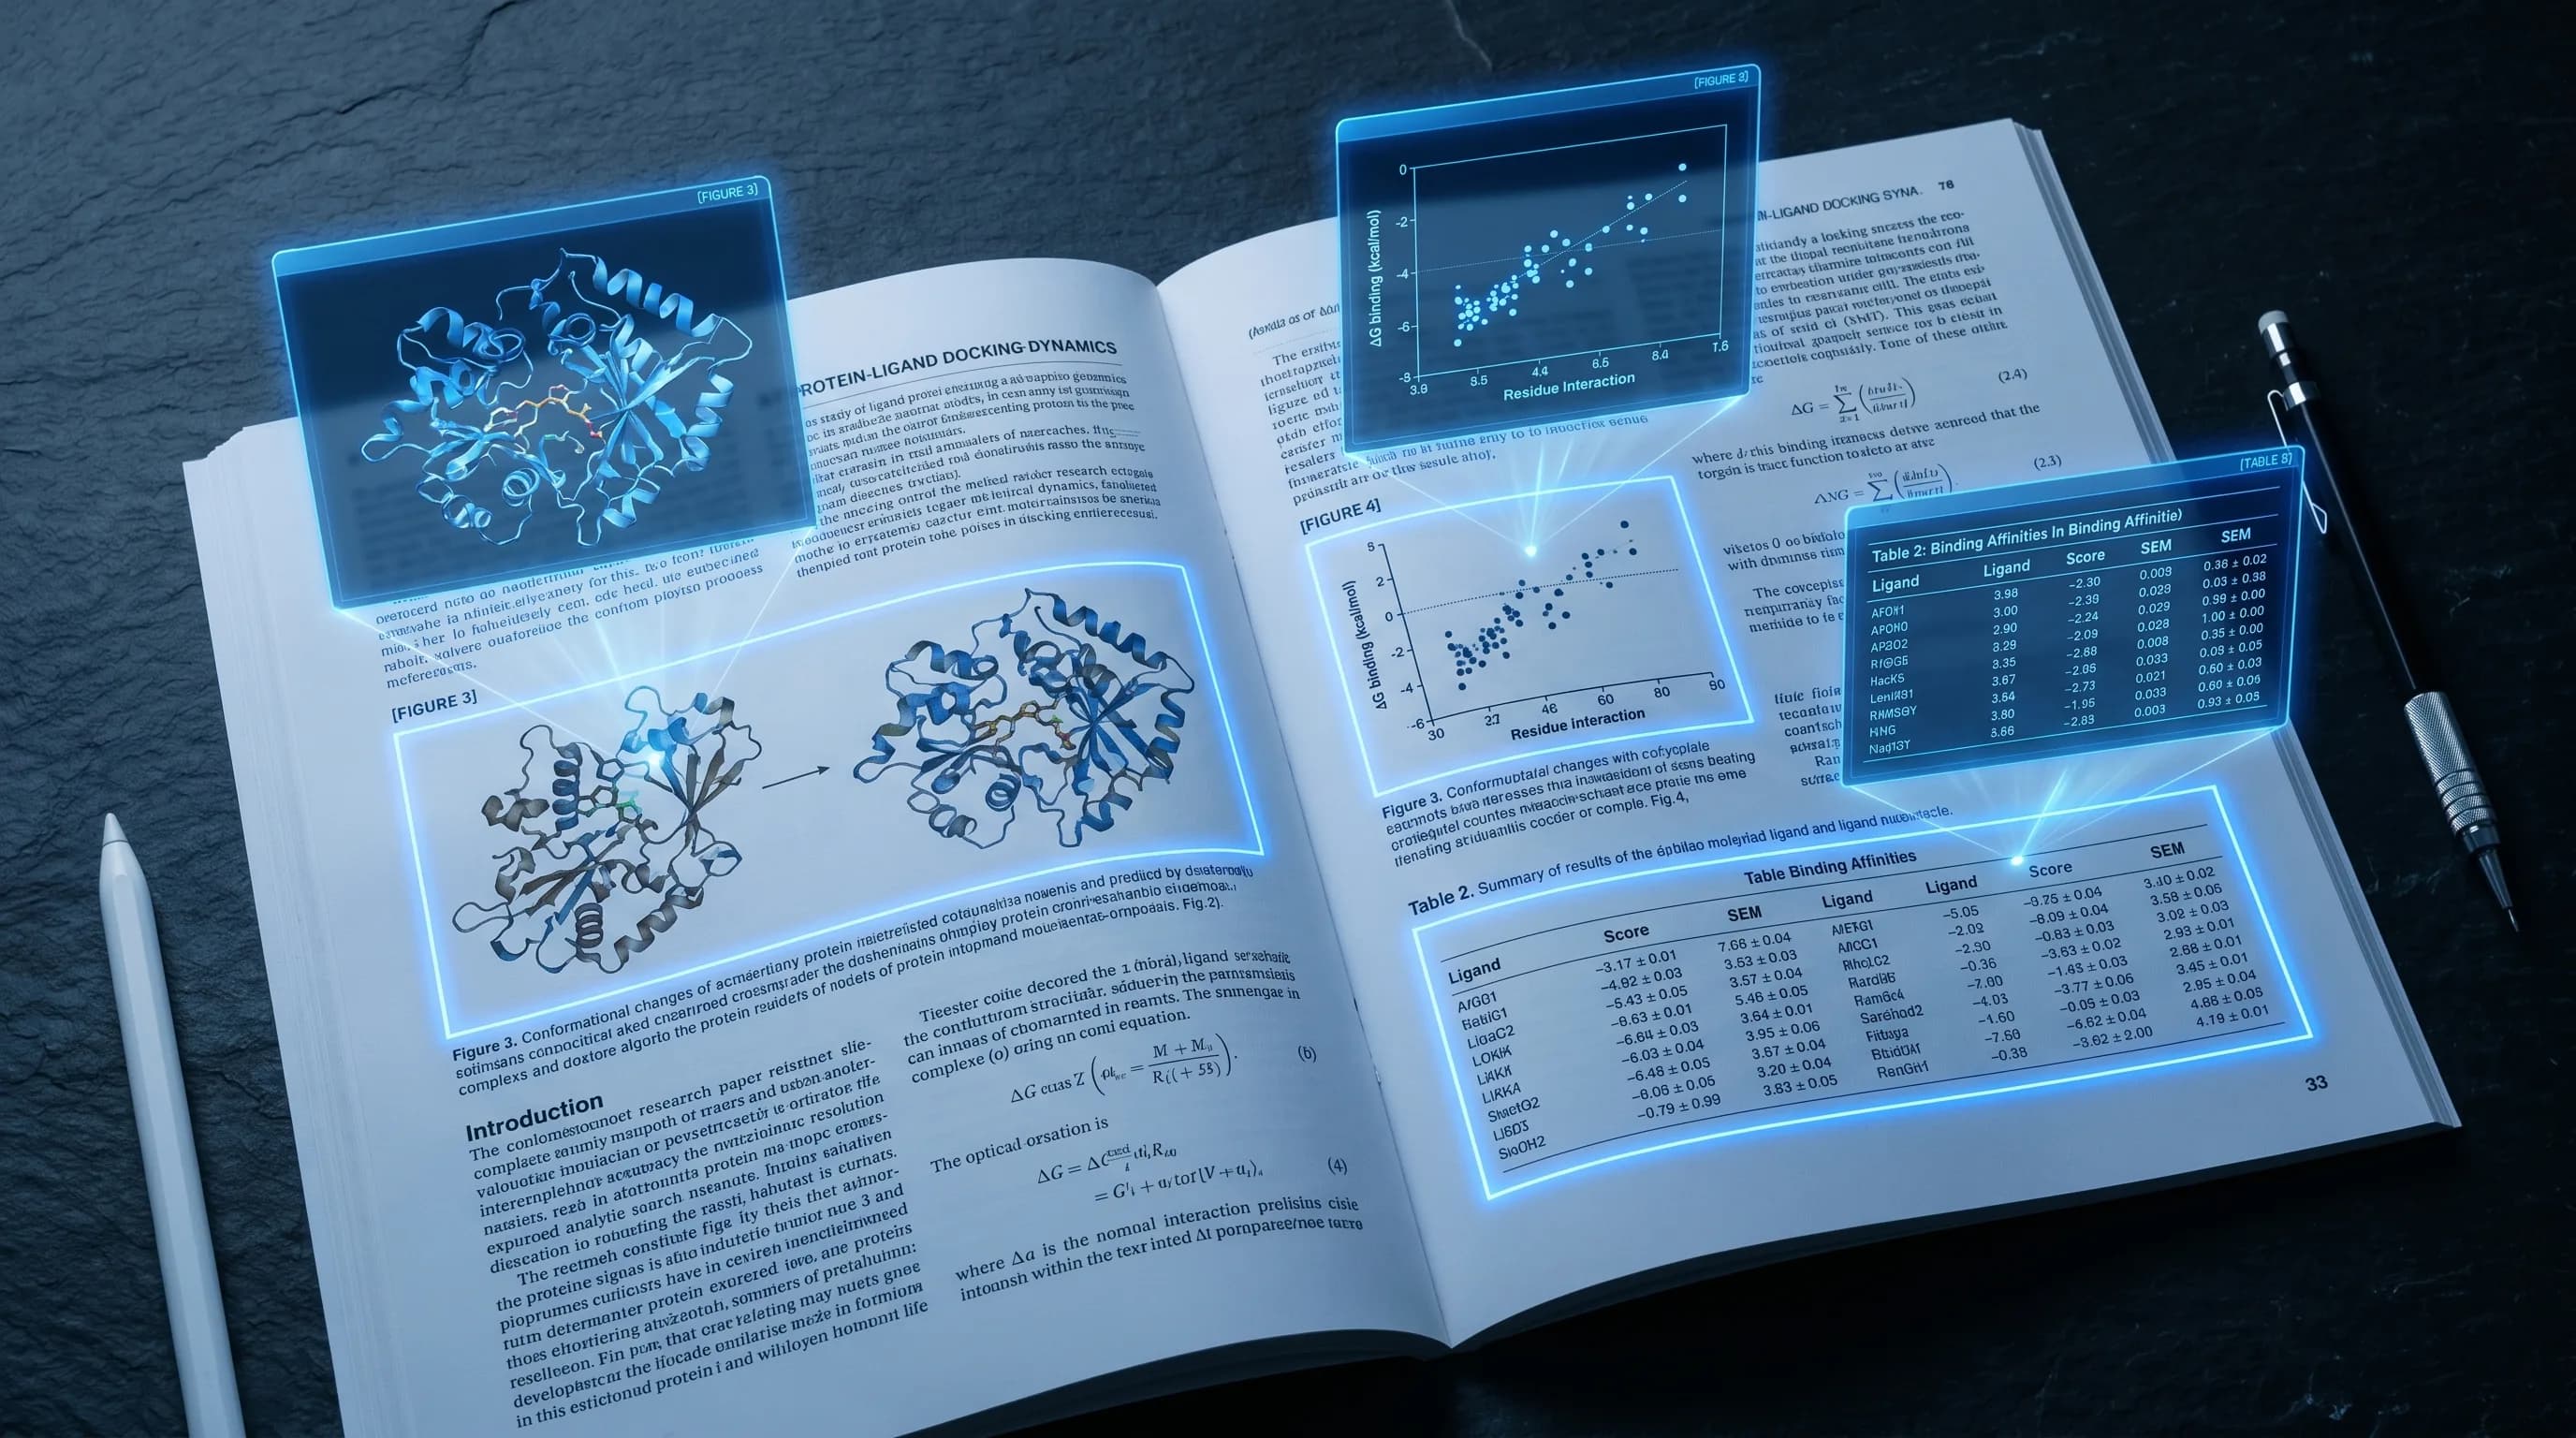
In a pharma R&D engagement, we watched a text-only RAG pipeline confidently answer a dosing question while the actual evidence, a dose-response curve and a table of adverse events, sat on the same page as image pixels the retriever never saw. The system was not wrong by accident. It was wrong by design, because the ingestion step had already discarded the highest-value content before a single embedding was computed.
In scientific and technical documents, the load-bearing claims live in figures, charts, and tables. A PDF-to-text extractor flattens those into nothing, or worse, into garbled fragments of axis labels. Your retriever then ranks prose that merely refers to a figure, and your model answers from the caption instead of the data. For regulated research, that is not a quality gap. It is an audit failure waiting to surface.
If your RAG system answers from prose while the evidence sits in the figures, you are not retrieving your documents. You are retrieving their captions.
Why text-only ingestion silently fails
Most pipelines run a single text extraction pass and treat anything non-textual as noise. Three failure modes follow. Tables lose their row and column structure, so a value detaches from its header and its units. Charts vanish entirely, taking the trend or threshold with them. Multi-column and multi-figure layouts get linearised into the wrong reading order, fusing unrelated paragraphs into one chunk. None of these throw an error. The pipeline reports full coverage while half the meaning is gone.
Extract with a vision model, not an OCR pass
The fix is to treat each page as an image and let a vision-capable model read it. In our pharma build we ran page renders through GPT-4 Vision and GPT-4o to produce a structured representation: figures described and the underlying values transcribed, tables emitted as Markdown or JSON with headers intact, and chart trends stated explicitly so they become retrievable text. OCR alone does not get you here. OCR returns characters. A vision model returns the relationship between a curve, its axes, and the claim the figure supports, which is what a researcher actually queries against.
Keep the rendered page image and its bounding boxes alongside the extracted text. You will need them for citation, and they let a reviewer confirm the model transcribed a number correctly rather than hallucinated it. Do not throw the pixels away a second time.
Chunk on structure, embed for both modalities
Structure-preserving chunking is the difference between a retriever that finds the evidence and one that finds the sentence next to it. A figure and its caption are one unit. A table and its header row are one unit. A results section stays whole rather than being split mid-argument by a fixed token window.
A workable decision rule: never let a chunk boundary cut through a table or separate a figure from its caption; split on document structure first, then fall back to token limits only inside a section. Embed the vision-extracted descriptions as text so charts and tables become first-class retrieval targets, and use text-embedding-3-large with a vector store such as Pinecone. Carry the page number, figure ID, and bounding box as metadata on every chunk.
Page and figure citations are the product
For regulated research, an answer without a verifiable source is unusable. Every generated claim should resolve to a page number and, where it came from a figure or table, the specific figure ID and the cropped region. We render the cited crop back to the reviewer so they can confirm the model read the right cell of the right table. This turns the system from a plausible-text generator into a reference-cited tool a scientist will actually trust, because trust here means being able to check the source in seconds.
Evaluate extraction before you evaluate answers
Most teams evaluate RAG end to end: ask a question, judge the answer. With multimodal corpora that hides the failure layer, because a wrong answer might be bad retrieval, bad generation, or a figure that was never extracted at all. Split the evaluation. First, an extraction audit: sample pages with known tables and charts, and score whether the transcribed values match the pixels. Second, a retrieval check against a golden set of questions whose evidence you know lives in a figure, scoring whether the figure chunk ranks in the top results. Only then judge answers. In our build, the majority of early failures were extraction misses, invisible to any answer-level metric until we measured the layer directly.
The audit also tells you when you are done. When the extraction pass stops finding new figure types it mishandles, and the golden-set retrieval rate stabilises, further model spend goes to the generation layer where it now actually matters, instead of compensating for evidence that was never there.
What it buys the business
In the pharma R&D engagement, literature reviews that took researchers weeks dropped to hours, and the answers came back with citations down to the figure. The reason it worked was not a larger model. It was refusing to discard the charts, figures, and tables at ingestion, the exact content the questions were really about. One budgeting note: vision extraction reads every page once at ingestion, so its cost is a one-time function of corpus size, while the retrieval and answer path stays cheap per query. Paying it is almost always better economics than paying researchers to keep re-finding what the pipeline threw away.


